Stop wasting hours slicing out verbal stumbles, retake restarts, and mouth clicks in complex audio software. VClar polishes your spoken delivery in fifteen seconds so casting directors, agents, and clients focus entirely on your dramatic performance.
Direct Answer: Voice actors frequently lose casting opportunities because high-end condenser and shotgun microphones capture involuntary vocal stumbles, hesitation pauses (“um,” “er”), saliva mouth clicks, and harsh breath spikes. Traditionally, removing these flaws required spending thirty to sixty minutes manually cutting waveforms in Pro Tools, Logic Pro, Reaper, or iZotope RX, or re-recording ten consecutive takes until vocal fatigue set in.
VClar solves this by acting as an automated, intelligent sound engineer. It processes your recorded vocal performance, excises line restarts and hesitation fillers, smooths salivary artifacts, and balances conversational pacing while preserving 100% of your genuine vocal timbre, pitch dynamics, emotional nuance, and character acting. Voice actors record in a single authentic take, polish the audio in fifteen seconds, and submit four times as many audition tapes every day.
In commercial voiceover, animation casting, and audiobook publishing, voice talent who submit early with pristine audio book the lion’s share of lucrative contracts.
According to casting insights documented by organizations like Backstage, casting directors review up to five hundred auditions for a single national commercial spot. If an audition tape opens with an insecure slate, a flubbed word, or noticeable mouth saliva clicks, the file is rejected before the actor reaches the core tagline.
When voice artists attempt to record a flawless, error-free take organically, they often record the same thirty-second copy eight to twelve times. By take seven, vocal cords become strained, throat dryness creates audible clicks, and emotional spontaneity collapses into mechanical, stiff cadence.
Voice artists are trained actors, not full-time mastering technicians. Spending forty-five minutes inside Pro Tools, Audacity, or Reaper manually chopping breath spikes, nudging crossfades, and erasing flubbed consonants robs valuable creative energy that should be spent rehearsing new scripts and marketing to production houses.
Compare raw scratch takes, traditional manual DAW surgery, synthetic AI voice cloning, and VClar neural speech polish across five critical performance metrics.
| Workflow Dimension | Raw In-Booth Scratch Read | Manual DAW Waveform Editing | Synthetic AI Voice Cloning | VClar Neural Audio Polish |
|---|---|---|---|---|
| Turnaround Speed | Immediate, but unpolished | 30–60 mins per audition | Instant generation | 15 Seconds (Instant 1-Take) |
| Vocal Nuance & Acting Emotion | 100% Organic, but flawed | 100% Organic (high effort) | 0% Robotic uncanny valley | 100% Preserved (True Human Craft) |
| Mouth Click & Saliva Artifacts | Audible & distracting | Requires manual spectral brush | Not applicable (synthetic) | Automated Acoustic Suppression |
| Filler & False Start Excision | Requires complete retake | Manual razor tool & room crossfades | Not applicable (script-generated) | Intelligent Neural Removal |
| Industry & Union Compliance | Accepted, but uncompetitive | Standard studio practice | Banned by SAG-AFTRA casting | 100% Union Compliant Artist Tool |
| Audition Submission Volume | Low (burnout from multiple takes) | 2–3 auditions per day max | High, but rejected by directors | 10–15 Auditions Daily |
Engineered for voice talent, audio directors, and narrators who need broadcast-ready delivery while preserving authentic emotional nuance and artistic expression.
Never sacrifice your vocal signature. VClar processes the actual acoustic waveform, guaranteeing that your warm baritone, airy whisper, comedic squeak, or gritty gravel remains 100% unadulterated.
If you stumble on a tricky corporate acronym or tongue-twisting brand slogan, simply pause, restate the sentence naturally, and continue. VClar excises the flubbed phrase and stitches seamless room tone.
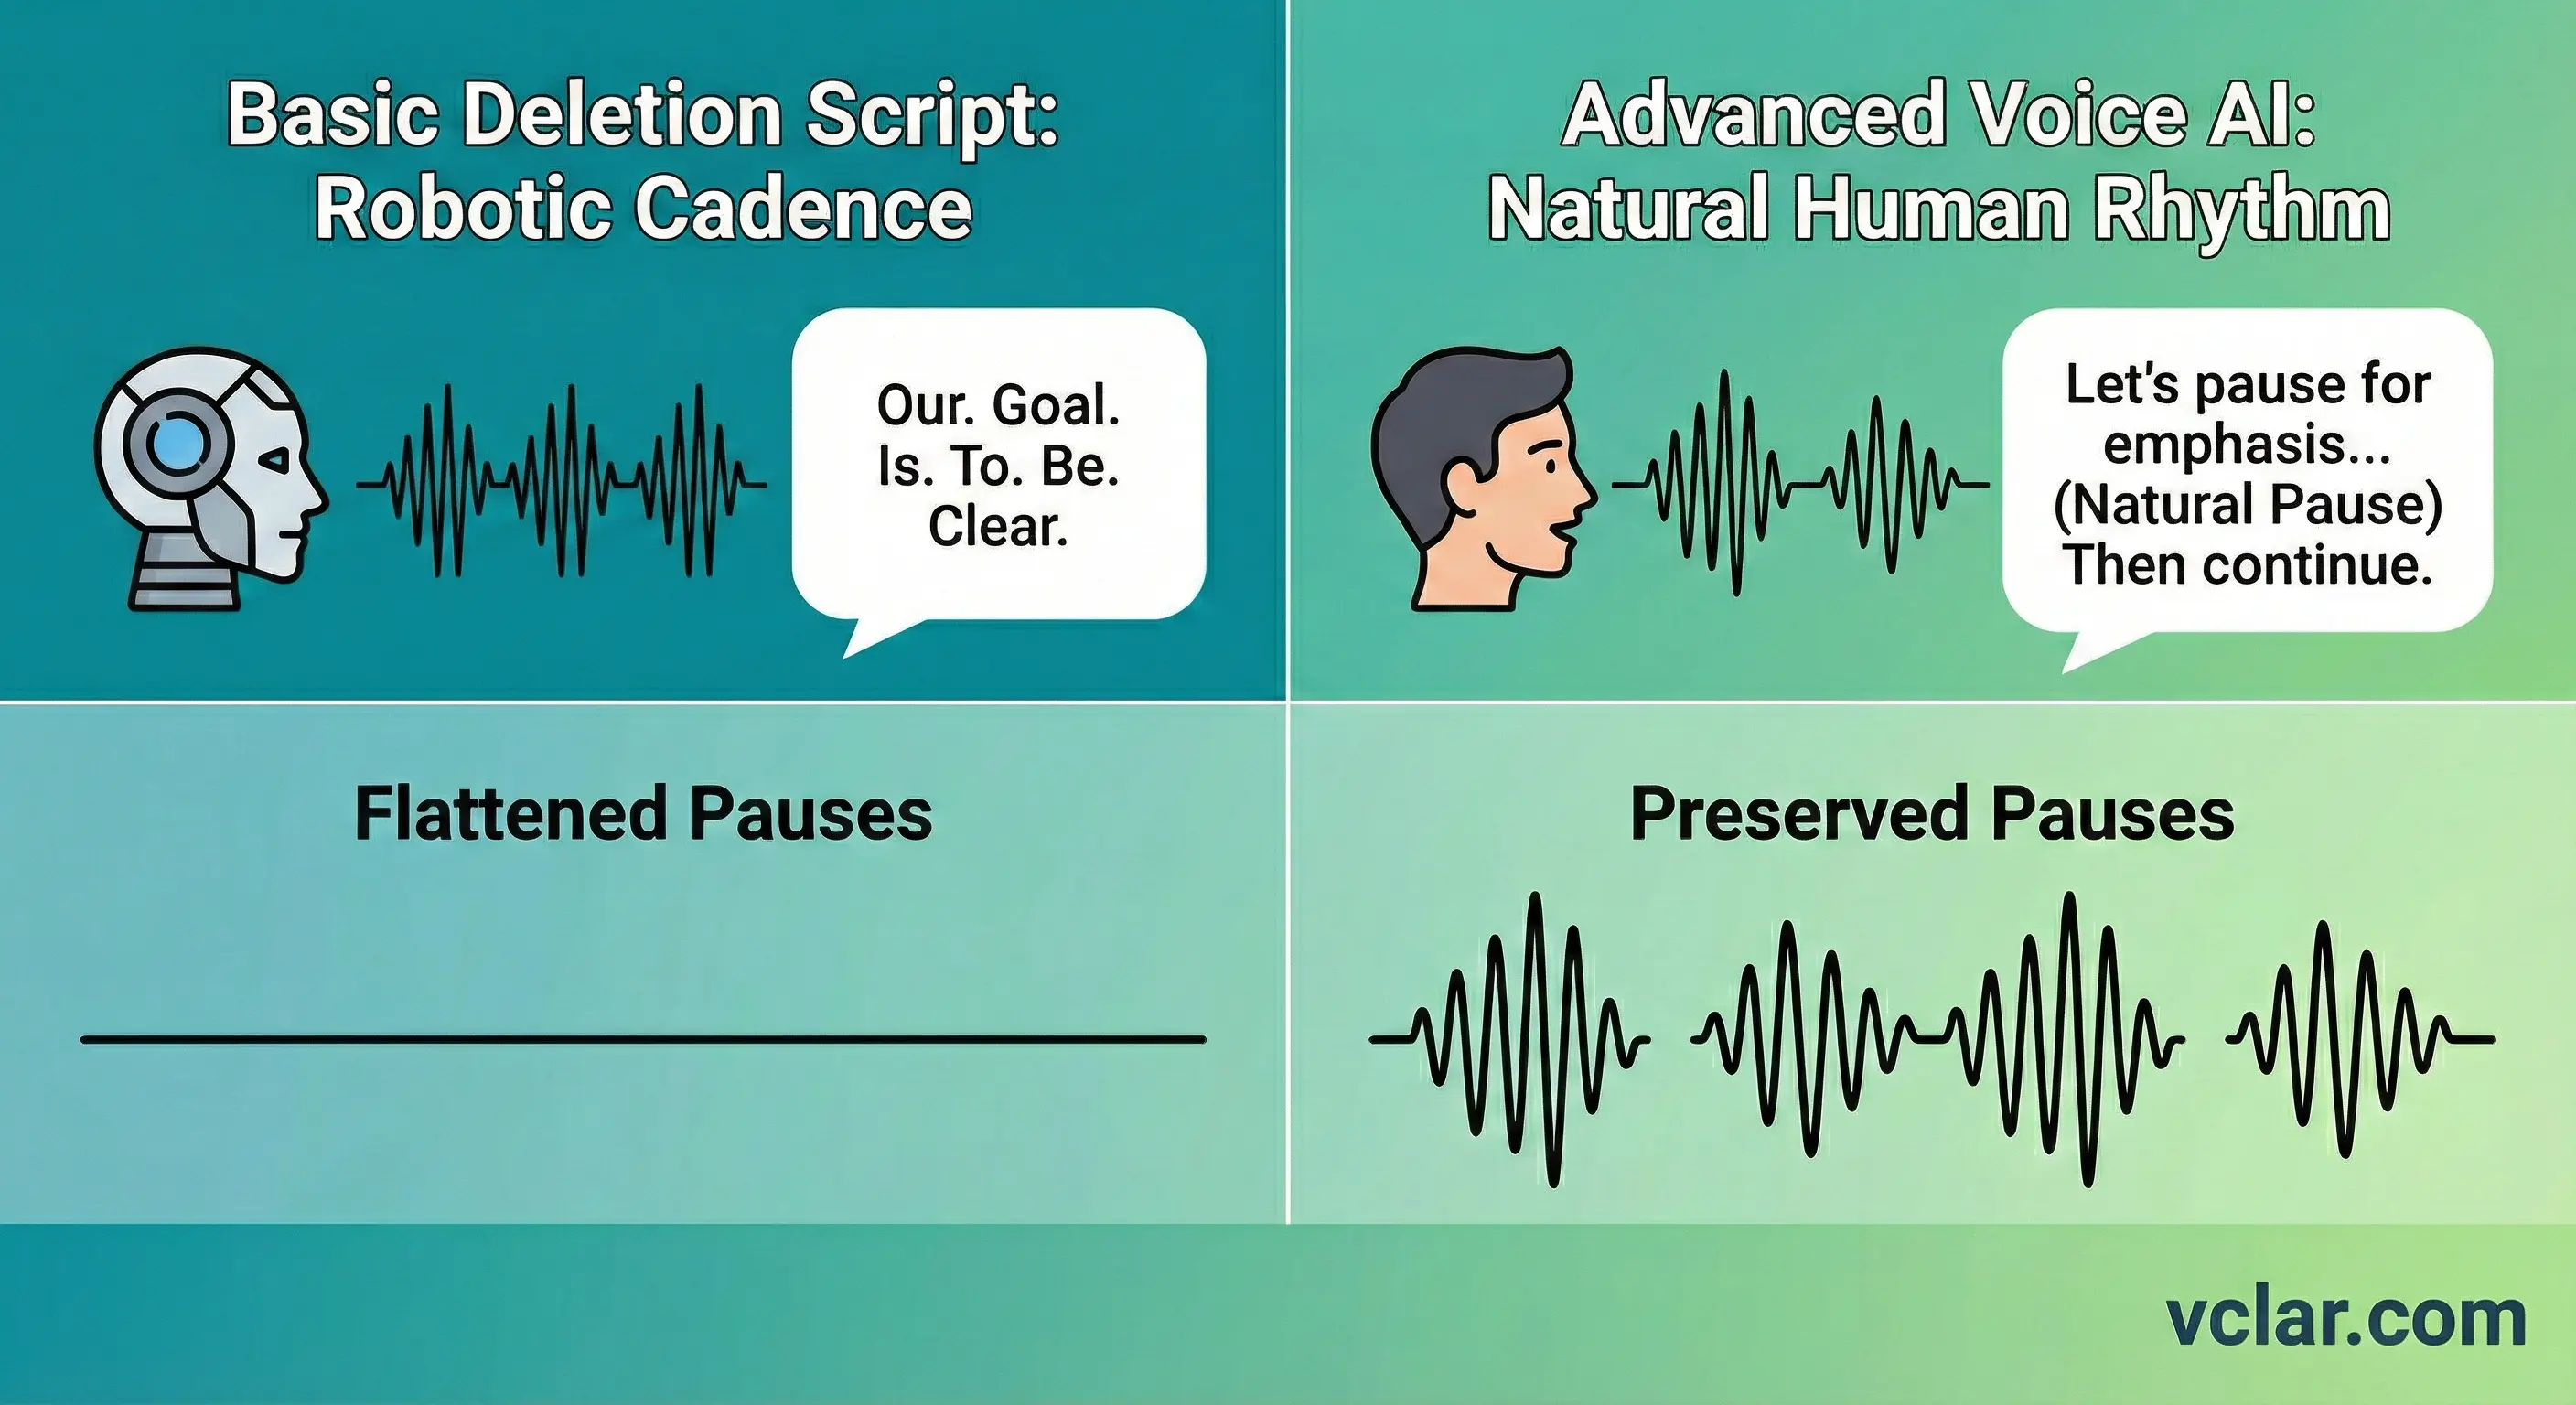
Acting is in the subtext. Dramatic pauses, intentional breaths before an emotional reveal, and playful inflection shifts are preserved with micro-second accuracy—never truncated by blunt noise gates.
High-sensitivity microphones like the Neumann U87 or Sennheiser MKH 416 ruthlessly capture lip smacks, saliva pops, and heavy inhalations. VClar suppresses these micro-distractions automatically.
Receive uncompressed studio-ready audio alongside a verbatim, grammatically synchronized text transcript. Perfect for client approvals, copy checks, and closed-caption alignment.
Deliver rapid revisions and alternate spec reads within minutes of receiving director feedback. By slashing editing overhead, voice talent can submit three distinct variations in the time it used to take for one.
Whether you specialize in thirty-second broadcast commercials, multi-hour audiobook sagas, dynamic character acting, or technical corporate explainers, VClar adapts to your specific vocal demands.
Commercial slating requires crisp energy, zero hesitation, and immediate vocal engagement. If an actor fumbles their name, agency representation, or introductory slate copy, the casting agent clicks forward.
Audiobook narrators face grueling recording schedules where reading ten thousand words consecutively leads to mid-sentence stumbles, dry mouth crackles, and fatigue.
Interactive voice acting demands extreme vocal extremes—from gritty battle fatigue to quirky, high-pitched comedic fantasy sidekicks.
Technical corporate narration features dense multi-syllabic terminology, pharmaceutical brand names, and complex financial metrics where mispronunciations occur easily.
Examine how VClar takes raw, stumbled home-studio audition reads and turns them into broadcast-grade submissions without sacrificing one decibel of acting emotion.
“Uh, hi. This is, um, Marcus Vance reading for the national Apex Hybrid spot, take one. [heavy inhale] Some roads aren't just paved... er, wait, let me start that line over. [lip smack] Some roads aren't just paved with asphalt. They are paved with ambition. The all-new Apex... like, delivers zero emissions without, uh, compromising on raw horsepower. Apex. Drive your tomorrow, today.”
Errors Detected: Insecure slate opening with filler words, heavy mic inhale before sentence one, mid-read verbal restart (“wait, let me start that line over”), audible salivary lip smack, and hesitations during the key technical specs.
“Marcus Vance reading for the Apex Hybrid spot. Some roads aren't just paved with asphalt—they are paved with ambition. The all-new Apex delivers zero emissions without compromising on raw horsepower. Apex. Drive your tomorrow, today.”
Result: Crisp 21-second broadcast-ready spot. Slate is authoritative, line restart and mouth clicks completely excised, room tone seamlessly crossfaded, and the actor’s resonant, warm baritone preserved 100% intact.
“By the winter of 1914, the diplomatic corps had, uh, basically exhausted all avenues of arbitration. [mouth click] Sir Edward Grey stood at his window in Whitehall, watching the lamplighters below. He turned to his companion and said, er, 'The lamps are going out all over Europe... we shall not see them lit again.' [throat reset] 'We shall not see them lit again in our lifetime.'”
Errors Detected: Conversational filler “basically” inserted into formal historical narrative, audible salivary click before quote, verbal hesitation “er,” and throat clearing reset on the famous Sir Edward Grey quote repetition.
“By the winter of 1914, the diplomatic corps had exhausted all avenues of arbitration. Sir Edward Grey stood at his window in Whitehall, watching the lamplighters below. He turned to his companion and said: 'The lamps are going out all over Europe. We shall not see them lit again in our lifetime.'”
Result: Deep, gravitas-rich narration meeting strict ACX standards. Cut 22 seconds of dead air and flubbed restarts while maintaining the narrator’s poignant dramatic pauses and authentic vocal solemnity.
“[raspy villain voice] You think your kingdom can withstand the frost? [tongue click] [whisper] Look upon the frozen towers of Valdoria. Um, their knights... [cough reset] their knights knelt before my blade before dawn broke. Surrender the relic, or your blood will join the permafrost.”
Errors Detected: Involuntary tongue click preceding whisper transition, out-of-character hesitation filler “um,” and an awkward mid-sentence cough/reset during the peak dramatic threat.
“[raspy villain voice] You think your kingdom can withstand the frost? Look upon the frozen towers of Valdoria. Their knights knelt before my blade before dawn broke. Surrender the relic, or your blood will join the permafrost.”
Result: Chilling villainous performance. The gravelly vocal fry, sinister breath timing, and menacing whispers are 100% intact, with all coughs, tongue clicks, and line hesitations surgically eliminated.
Standard digital audio workstations require voice artists to wear two conflicting hats: emotional performer and tedious audio editor. See how VClar liberates your workflow.
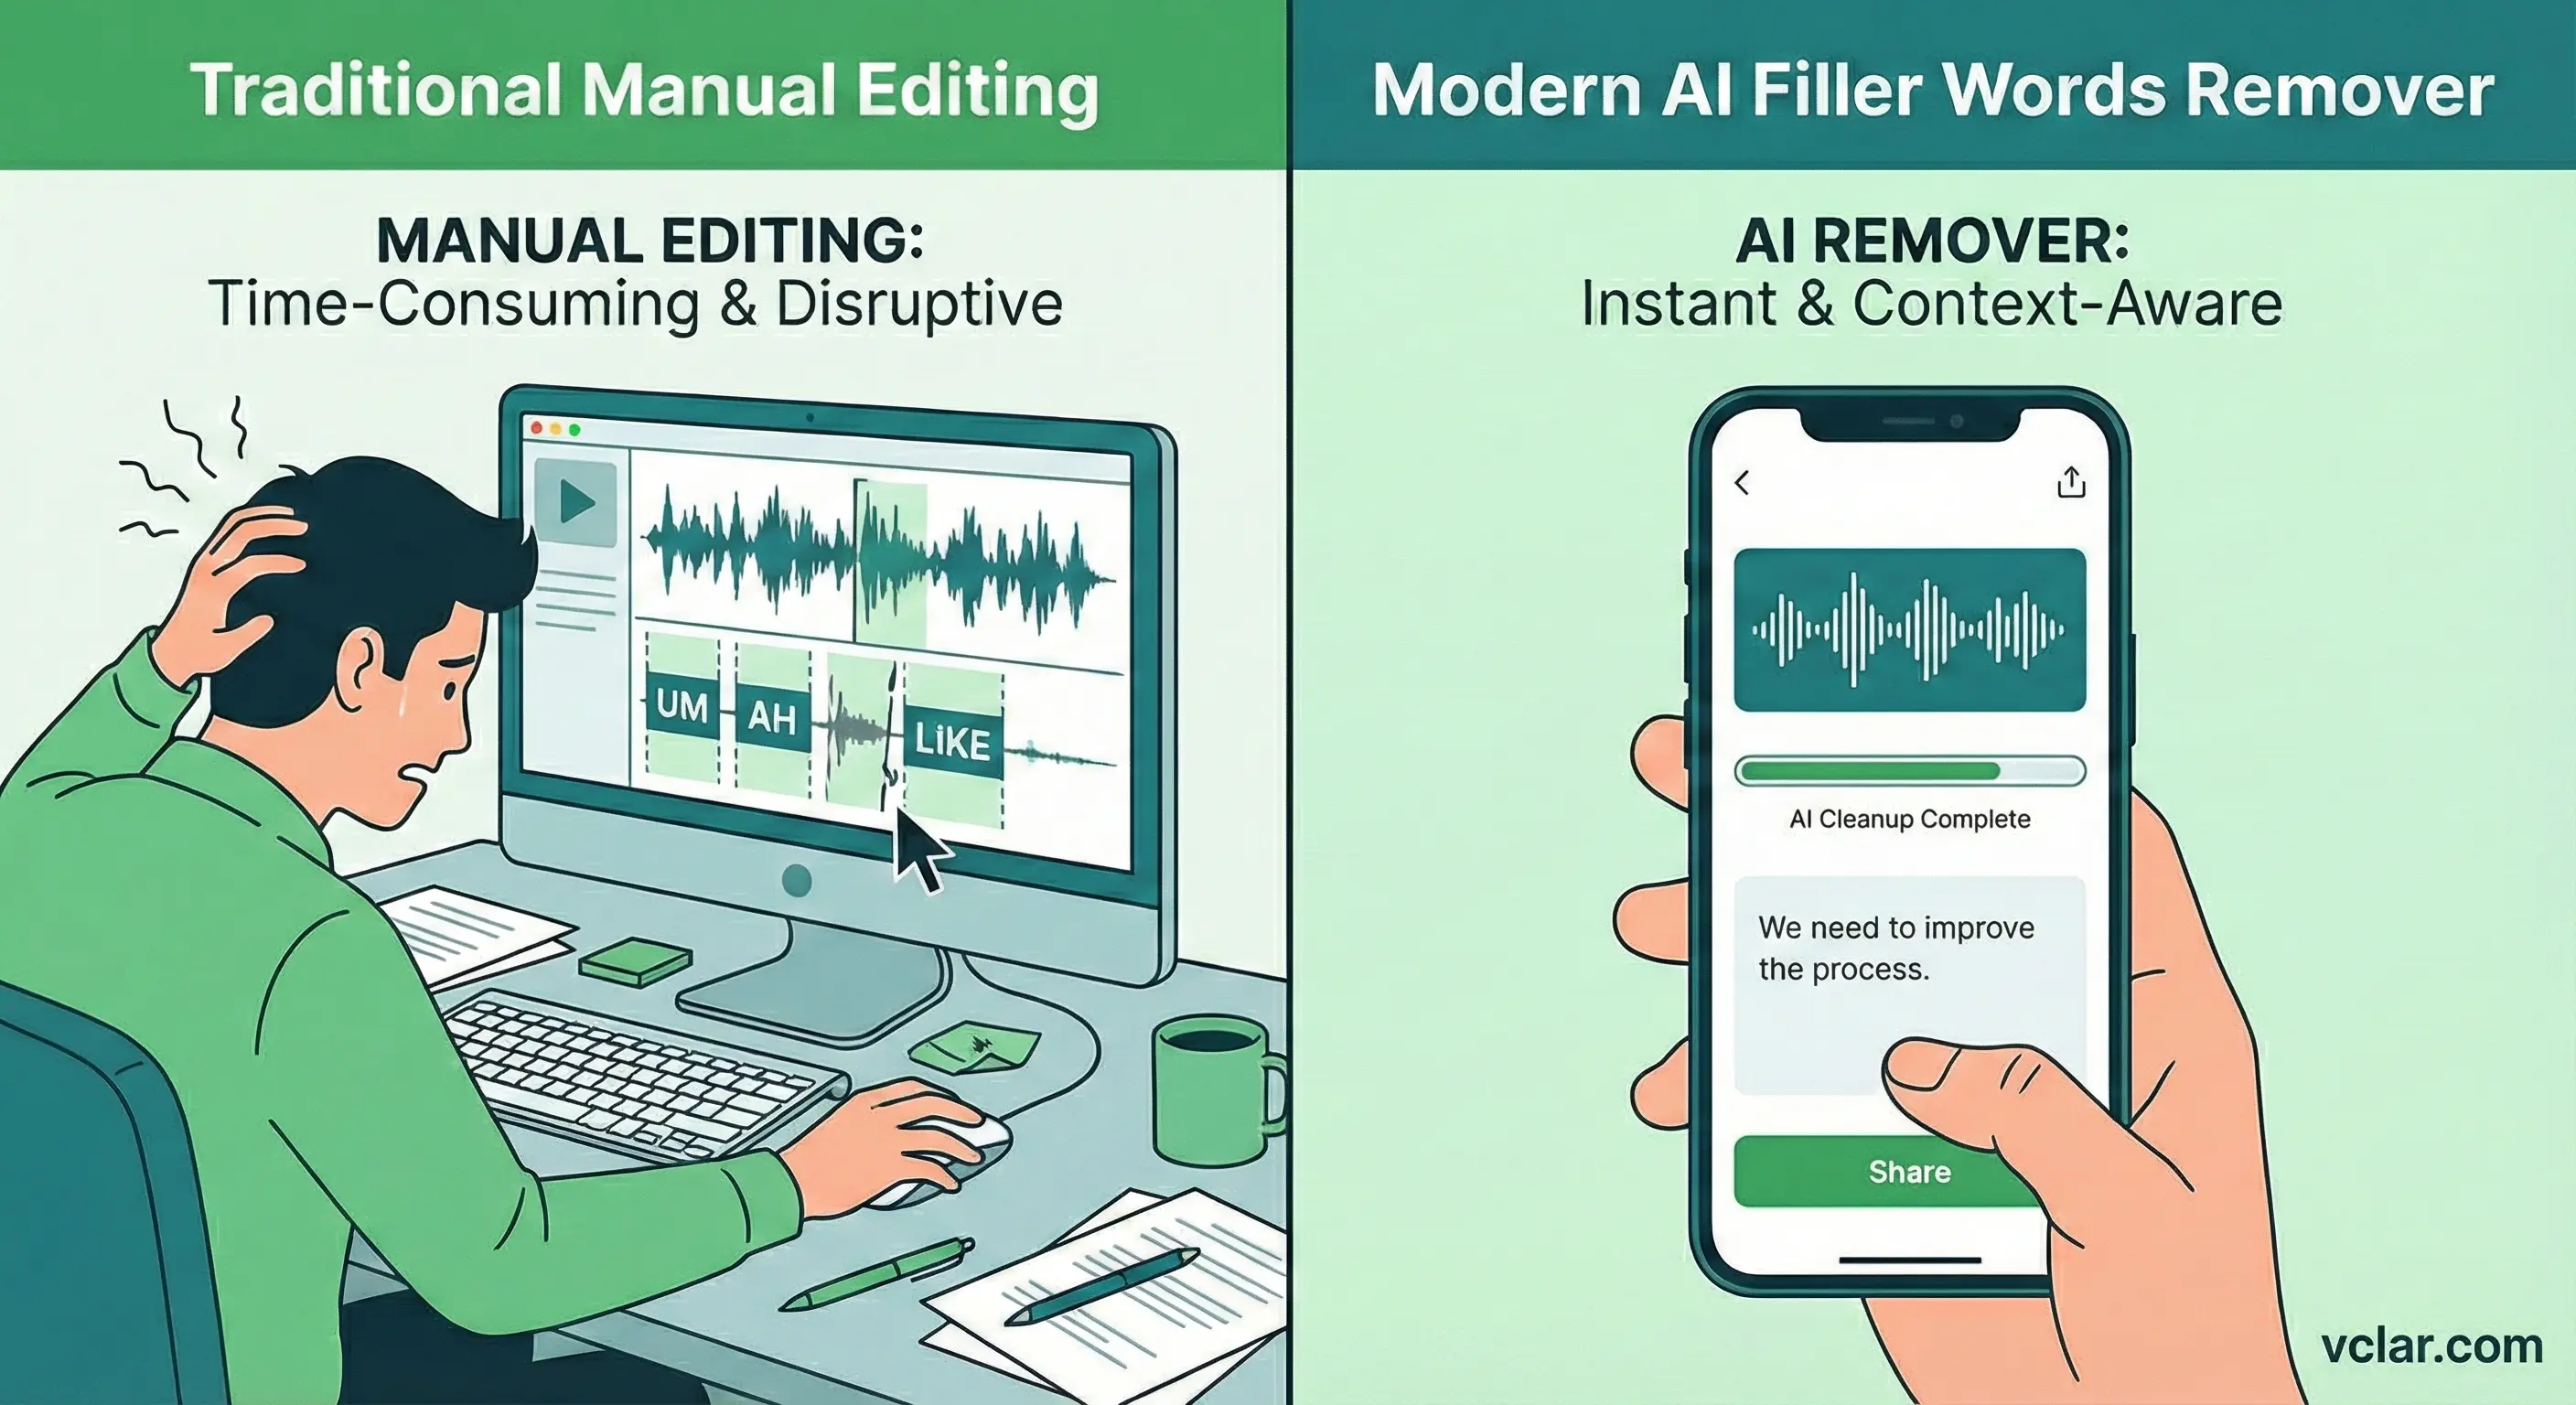
Professional voice actors affiliated with organizations like SAG-AFTRA and the Society of Voice Arts and Sciences (SOVAS) understand that acting booking rates are a direct function of audition volume multiplied by quality of delivery. When you spend forty-five minutes editing a sixty-second audition, your daily output is capped at three or four auditions before mental fatigue sets in.
By delegating the mechanical excision of stumbles, mouth clicks, and hesitation pauses to VClar, voice actors can audition for ten to fifteen roles every afternoon with zero drop in vocal quality or submission polish.
The primary telltale sign of an amateur voiceover edit is unnatural room tone dropout. When a voice talent manually cuts out an 'um' or breath in Audacity or Reaper without applying precise micro-crossfades, the ambient room tone cuts out completely, creating jarring digital silence gaps that immediately trigger casting director fatigue.
VClar replaces clumsy razor cuts with neural room-tone continuity synthesis. When an involuntary stumble or filler sound is excised, VClar analyzes the ambient acoustic profile of your home studio or vocal booth—matching the exact natural reverberation and background noise floor—and bridges the edit with seamless acoustic continuity. Listeners hear one uninterrupted, cohesive stream of natural speech.
Unlike basic speech-to-text tools or robotic noise reduction plugins that over-compress audio waveforms and clip resonant harmonics, VClar preserves professional dynamic headroom. Voice actors reading dynamic dialogue—moving from an intimate stage whisper at -30 dBFS to an authoritative call-to-action peak at -6 dBFS—maintain full acoustic fidelity.
Whether you are submitting an MP3 spec read to an agency casting director, exporting a commercial spot meeting EBU R128 (-23 LUFS) broadcast loudness guidelines, or mastering long-form non-fiction chapters for the Audible Creation Exchange (ACX) between -23 dB and -18 dB RMS, VClar delivers pristine audio that integrates directly into your master chain.
Audio engineers and casting directors flag these five delivery flaws within seconds of opening an audition file.
Opening an audition with hesitant chitchat (“Uh, hi there, hope everyone's having a great Tuesday...”) drains the director's patience. VClar tightens slates to three confident seconds: name, agency, role.
Even well-hydrated voice actors produce subtle saliva pops on plosive consonants (“p,” “b,” “t”). High-end studio headphones amplify these into jarring distractions that VClar suppresses.
Accidentally submitting an audition tape that contains a mumbled sentence restart reveals sloppy self-direction. VClar identifies flubbed sentences and stitches room tone seamlessly.
Heavy gasps for air between long legal disclaimers or audiobook paragraphs sound amateurish. VClar gently attenuates breath surges to natural human levels without creating artificial silence gaps.
Casting directors often close talent portals once the first fifty quality auditions arrive. Taking two hours to edit your tape means your submission may never even be heard. VClar lets you submit within five minutes.
Record with bold acting intent. Focus entirely on emotional truth and dramatic objective. Let VClar eliminate the technical blemishes in fifteen seconds.
Discover how asynchronous voice notes, automated speech enhancement, and filler excision empower creators, instructors, founders, and solopreneurs worldwide.
Everything you need to know about vocal authenticity, union compliance, DAW workflows, ACX requirements, and character voice preservation.
No. VClar is not an artificial text-to-speech synthesizer or generic voice cloning model. It processes your real recorded acoustic waveform, preserving 100% of your organic vocal resonance, emotional inflection, whisper dynamics, gravel, and pitch nuances. It strictly removes non-essential vocal friction such as hesitation sounds ('um', 'uh'), false line starts, and salivary mouth clicks while maintaining your authentic artistic craft.
Commercial casting directors and talent agents review hundreds of audition submissions per role. When an audition begins with an awkward five-second pause, a stumbling slate, noticeable mouth clicks, or breath gasps, it signals lack of professional studio discipline. Casting directors immediately skip to the next audition. A polished, punchy, immediate read captures attention within the critical seven-second window.
Traditional digital audio workstation (DAW) editing requires zooming into spectral waveforms to manually slice out retakes, align room tone crossfades, and apply de-click and de-breath plugins. Splicing a three-minute audition can take thirty to forty-five minutes. VClar automates this process in fifteen seconds with intelligent acoustic neural models, freeing voice actors to audition for five times as many roles each day.
Yes. VClar's models are trained to differentiate between deliberate artistic vocal performance—such as character rasps, dramatic whispers, dialect inflections, and comedic timing—and involuntary speech clutter like hesitation fillers and nervous throat resets. Your character voices remain completely intact.
Yes. VClar exports high-bitrate MP3 and uncompressed WAV files with clean noise floors, consistent RMS levels, and natural room tone continuity. By eliminating mouth clicks, saliva crackles, and unnatural retake splices, VClar ensures smooth listening continuity required by audiobook publishers.
No. SAG-AFTRA protections specifically regulate synthetic voice generation that clones or replaces human performers without consent or compensation. VClar is an artist-controlled performance enhancement and post-production utility—it works solely on the performer's authentic audio recording to clean delivery and does not create synthetic likenesses or train generative public models.
Yes. VClar features bidirectional voice translation across ten major global languages (English, Spanish, French, German, Japanese, Korean, Portuguese, Italian, Russian, and Mandarin Chinese) across ninety language pairs, enabling voice talent to pitch international commercial campaigns and multilingual corporate projects.
Clean your audition tapes, commercial slates, and narration reads in fifteen seconds—with 100% of your authentic vocal timbre, dramatic nuance, and performance power intact.
No credit card required. Free tier includes 2 lifetime minutes. Instant export in MP3, WAV, and text.